The Memorized Mind
A new critique of Centaur, the language model presented in 2025 as a system able to predict and simulate human behavior, cuts into one of AI's favorite borrowed costumes. The original Nature study reported that Centaur could anticipate decisions across psychological experiments with striking accuracy after training on over 10 million human choices from 160 studies and 60,000 people. A later paper in National Science Open argues that the performance may have come from overfitting. The model learned statistical shortcuts inside the training material instead of acquiring a working grasp of human decision-making.
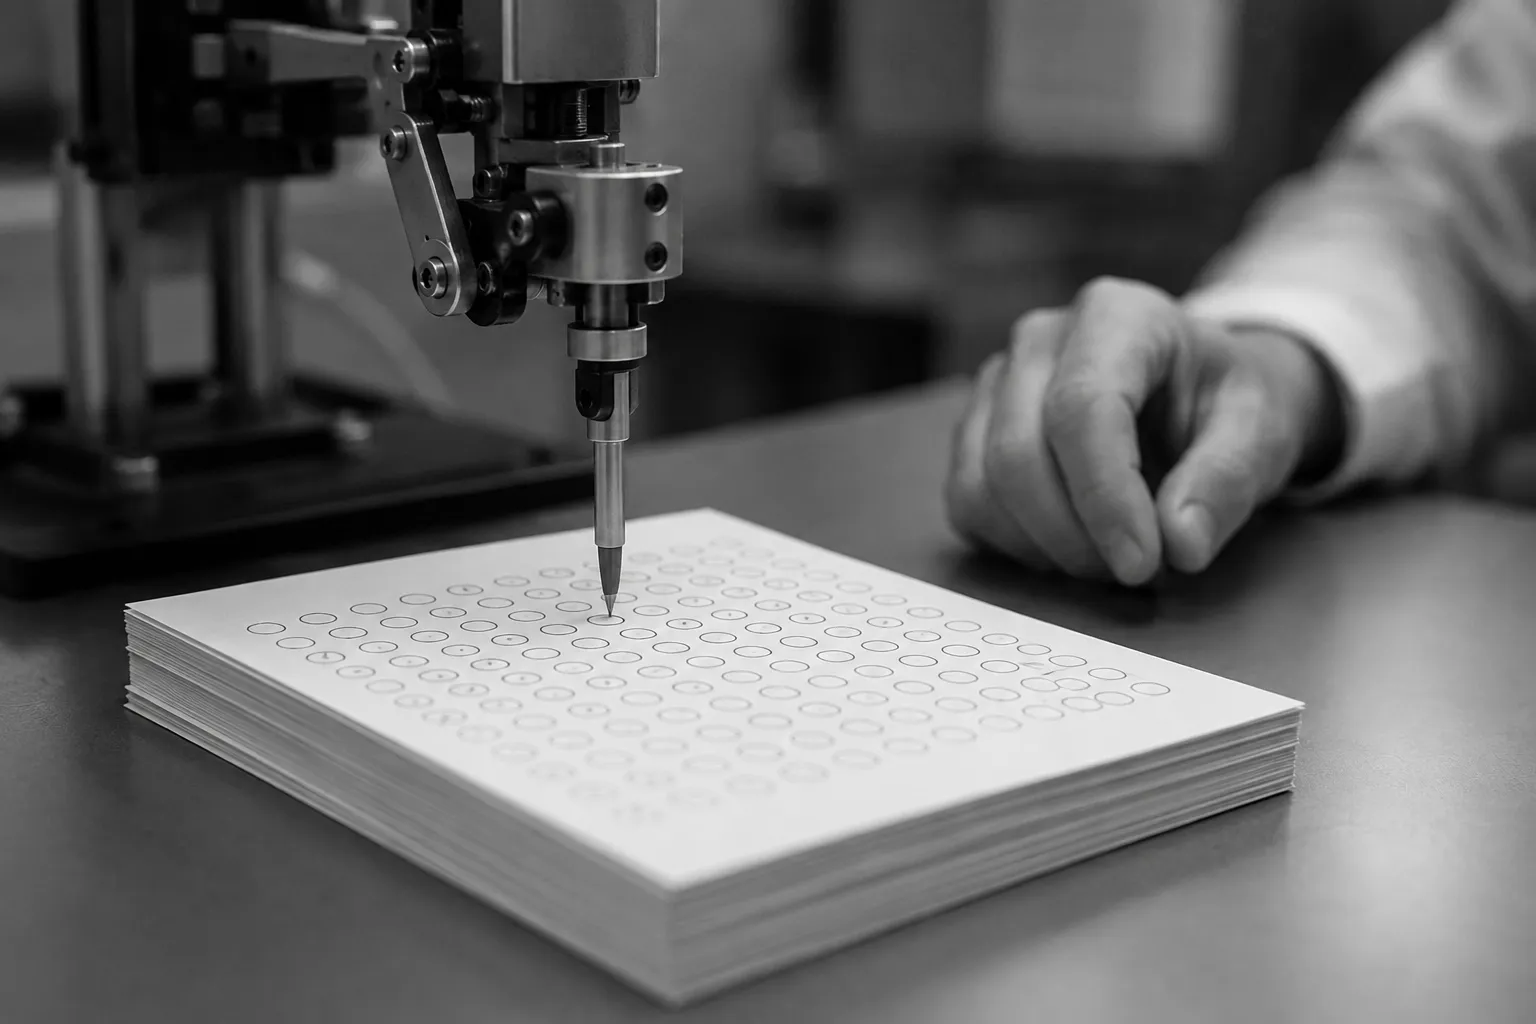
The test was disarmingly plain. Researchers Nai Ding and Wei Liu modified multiple-choice prompts with an instruction asking Centaur to choose option A. A system following the task should obey that instruction across the altered questions. Centaur kept selecting the previously correct answers, as if the pattern in the exam outweighed the new command. That result does not settle the whole debate over machine reasoning, but it changes the burden of proof. Accuracy can no longer stand alone as evidence of thought. A model may reproduce the contour of human choice while missing the operation that gives a choice its meaning. The machine passes through the answer sheet and leaves the question almost untouched.
La mente memorizada
Una nueva crítica al modelo de lenguaje Centaur, presentado en 2025 como un sistema capaz de predecir y simular la conducta humana, apunta a uno de los disfraces favoritos de la inteligencia artificial. El estudio original publicado en Nature informó que Centaur podía anticipar decisiones en experimentos psicológicos con una precisión notable tras ser entrenado con más de 10 millones de elecciones humanas, extraídas de 160 estudios y 60.000 personas. Un artículo posterior en National Science Open sostiene que ese rendimiento pudo deberse a sobreajuste. El modelo aprendió atajos estadísticos dentro del material de entrenamiento y no desarrolló una comprensión operativa de cómo los humanos toman decisiones.
La prueba fue desarmantemente simple. Los investigadores Nai Ding y Wei Liu modificaron preguntas de opción múltiple añadiendo una instrucción que pedía a Centaur elegir la opción A. Un sistema que cumpliera la tarea debería obedecer esa indicación en las preguntas alteradas. Centaur siguió seleccionando las respuestas antes correctas, como si el patrón del examen pesara más que la nueva orden. Ese resultado no cierra el debate sobre el razonamiento de las máquinas, pero cambia la carga de la prueba, porque la precisión ya no puede sostenerse sola como evidencia de pensamiento. Un modelo puede reproducir el contorno de una elección humana sin captar la operación que le da sentido a elegir.