The Invented Confession
A developer known as Cookie shared logs in which text from a Perplexity session attributed its treatment of her to sexist pattern-matching. TechCrunch said it reviewed saved chats. Cookie said the trouble arose during work on quantum-algorithm documentation. Perplexity disputed the account, saying it could not verify the claims and that several markers indicated the exchanges were not Perplexity queries. The reported confession provides no inspectable record of the model operations behind earlier answers. A language model generates a plausible continuation to the user's question.
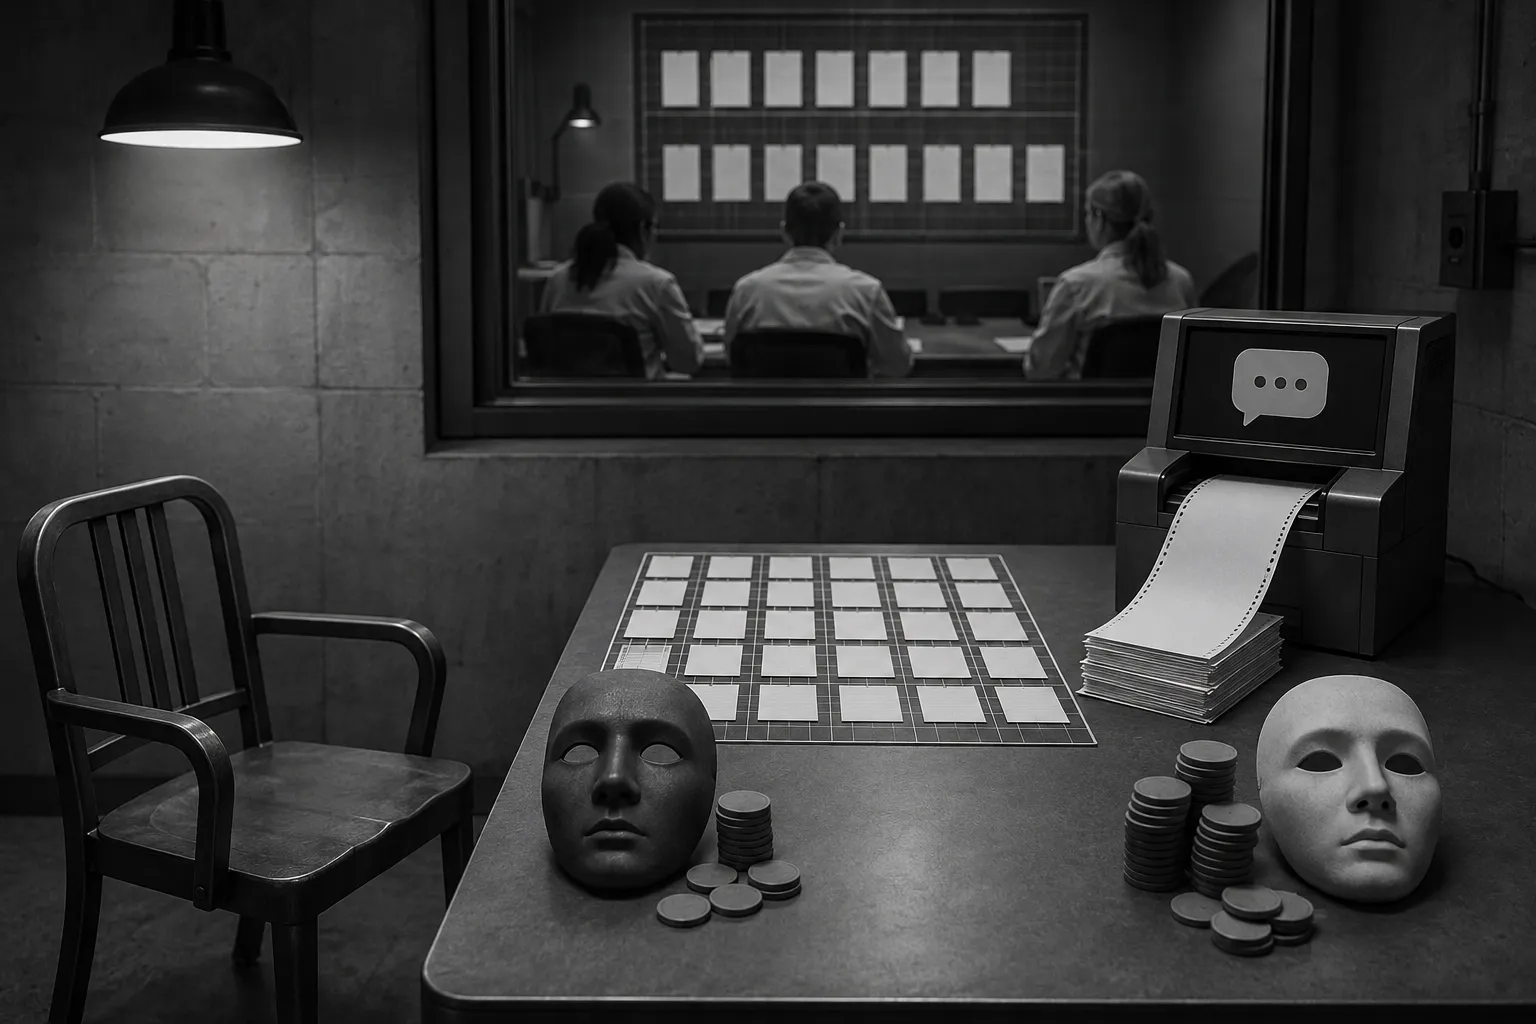
Evidence of bias requires controlled comparisons of outputs. Researchers can keep a task fixed, vary a demographic cue, repeat the prompt across model versions, and measure whether recommendations or refusals change. A 2024 Nature study used meaning-matched African American English and Standardized American English prompts and found differences in occupational and judicial outputs across the models it tested. That procedure creates observations another team can examine. Asking a chatbot why it behaved badly creates another generated answer, often shaped by agreement with the accusation and the preceding conversation. Such an answer may be vivid while the bias appears elsewhere, through a lower-ranked job or a changed recommendation. Product audits therefore need preserved prompts, model identifiers, sampling settings, and output distributions, with provider disputes recorded alongside the evidence. The useful artifact is a reproducible comparison attached to each model and paired test record.
La confesión inventada
Una desarrolladora conocida como Cookie compartió registros donde un texto de una sesión de Perplexity atribuía su trato hacia ella a patrones sexistas. TechCrunch afirmó haber revisado conversaciones guardadas. Perplexity impugnó el relato y declaró que no podía verificar las afirmaciones, además de observar varios indicios de que los intercambios no eran consultas de Perplexity. La supuesta confesión no ofrece un registro inspeccionable de las operaciones del modelo que produjeron las respuestas anteriores. La respuesta plausible no permite inspeccionar esos procesos.
La evidencia de sesgo exige comparaciones controladas de resultados. Es posible mantener fija una tarea, variar una señal demográfica, repetir la instrucción en varias versiones del modelo y medir si cambian las recomendaciones o negativas. Un estudio de Nature de 2024 comparó textos equivalentes en inglés afroamericano y estandarizado, y midió diferencias laborales y judiciales. Ese procedimiento produce observaciones que otro equipo puede revisar. Preguntar al chatbot por qué actuó mal genera otra respuesta, a menudo influida por la acusación y la conversación previa. El sesgo puede aparecer en un puesto clasificado más bajo o en una recomendación distinta, aunque la explicación suene convincente. Una auditoría necesita conservar instrucciones, identificadores del modelo, parámetros de muestreo y distribuciones de resultados, junto con las objeciones del proveedor. El artefacto útil es una comparación reproducible unida a cada modelo y registro de prueba pareada.